(async () => {

  // ====== UI skeleton ======
  const box = html`<div style="max-width:1080px;font:14px system-ui;">
    <div id="ctrl" style="display:grid;grid-template-columns:repeat(3,minmax(0,1fr));gap:10px;margin-bottom:10px;"></div>
    <div id="plot"></div>
    <div id="dash" style="display:grid;grid-template-columns:repeat(2,minmax(0,1fr));gap:10px;margin-top:10px;"></div>
    <div id="note" style="margin-top:6px;color:#444"></div>
  </div>`;
  const ctrl    = box.querySelector("#ctrl");
  const plotDiv = box.querySelector("#plot");
  const dash    = box.querySelector("#dash");
  const note    = box.querySelector("#note");

  // ====== Controls ======
  const algoS     = Inputs.select(["DBSCAN","K-means","Hierarchical"], {value:"DBSCAN", label:"Algorithm"});
  const seedS     = Inputs.range([1,9999],  {value: 1234, step: 1,    label: "Seed"});
  const nS        = Inputs.range([100,800], {value: 400,  step: 50,   label: "Points (n)"});
  const shapeS    = Inputs.select(["blobs","moons","circles"], {value:"circles", label:"Dataset"});
  const noiseS    = Inputs.range([0,0.3],   {value: 0.02, step: 0.01, label: "Noise ratio"});

  // K-means (no Max iters control; fixed at 50)
  const kS         = Inputs.range([2,12],   {value: 3,  step: 1, label: "k (K-means)"});
  const showElbow  = Inputs.toggle({label: "Show Elbow & Silhouette (K-means)", value: true});

  // DBSCAN
  const epsS      = Inputs.range([0.02,0.5],{value: 0.045, step: 0.005, label: "ε (eps)"});
  const minPtsS   = Inputs.range([3,30],    {value: 10,    step: 1,     label: "minPts"});
  const showKDist = Inputs.toggle({label: "Show k-distance (DBSCAN)", value: true});

  // Hierarchical
  const hkS        = Inputs.range([2,12],   {value: 3, step: 1, label: "k (Hierarchical)"});
  const linkageS   = Inputs.select(["single","complete","average","ward"], {value:"single", label:"Linkage"});

  const btnRes  = Inputs.button("Resample");

  // ====== Layout (3 columns) ======
  const col1 = html`<div></div>`;
  const col2 = html`<div></div>`;
  const col3 = html`<div></div>`;

  // Column 1: general
  col1.append(algoS, seedS, nS, shapeS, noiseS);

  // Column 2: DBSCAN block -> K-means block
  col2.append(
    epsS, minPtsS, showKDist,
    kS
  );

  // Column 3: Hierarchical + Resample + Show Elbow
  col3.append(
    hkS, linkageS,
    btnRes,
    showElbow
  );

  ctrl.append(col1, col2, col3);

  // ====== Utils ======
  const TAU = 2*Math.PI;
  const clamp = (x,a,b)=> Math.max(a, Math.min(b,x));
  function mulberry32(a){ return function(){ let t=a+=0x6D2B79F5; t=Math.imul(t^t>>>15,t|1); t^=t+Math.imul(t^t>>>7,t|61); return ((t^t>>>14)>>>0)/4294967296 } }
  function rnorm(rng, m=0, s=1){ let u=0,v=0; while(u===0) u=rng(); while(v===0) v=rng(); return m + s*Math.sqrt(-2*Math.log(u))*Math.cos(TAU*v); }
  function dist(a,b){ return Math.hypot(a.x-b.x, a.y-b.y); }
  function dist2(a,b){ const dx=a.x-b.x, dy=a.y-b.y; return dx*dx+dy*dy; }
  const colorFor = (cid)=> cid<0 ? "#888" : `hsl(${(cid*65)%360} 70% 45%)`;

  // ====== Data generators ======
  function genBlobs(n, rng){
    const k=3, centers = [{x:0.25,y:0.3},{x:0.7,y:0.35},{x:0.5,y:0.75}], sds=[0.06,0.07,0.05];
    const arr = [];
    for(let i=0;i<n;i++){
      const c = (rng()*k)|0;
      arr.push({ x: clamp(rnorm(rng, centers[c].x, sds[c]), 0,1),
                 y: clamp(rnorm(rng, centers[c].y, sds[c]), 0,1) });
    }
    return arr;
  }
  function genMoons(n, rng){
    const arr = [];
    for(let i=0;i<n;i++){
      const t = rng()*Math.PI;
      if(i<n/2){
        const r=0.28, cx=0.35, cy=0.5;
        const x = cx + r*Math.cos(t) + r*0.12*rnorm(rng);
        const y = cy + r*Math.sin(t) + r*0.12*rnorm(rng);
        arr.push({x: clamp(x,0,1), y: clamp(y,0,1)});
      }else{
        const r=0.28, cx=0.65, cy=0.5;
        const x = cx + r*Math.cos(t+Math.PI) + r*0.12*rnorm(rng);
        const y = cy + r*Math.sin(t+Math.PI) + r*0.12*rnorm(rng);
        arr.push({x: clamp(x,0,1), y: clamp(y,0,1)});
      }
    }
    return arr;
  }
  function genCircles(n, rng){
    const n1 = Math.floor(n/2), n2 = n - n1;
    const cx=0.5, cy=0.5;
    const r1 = 0.20, r2 = 0.40;
    const sRad = 0.010, sTan = 0.010;
    const pts = [];
    for (let i=0; i<n1; i++){
      const a  = rng()*2*Math.PI;
      const rr = r1 + sRad*rnorm(rng);
      pts.push({ x: clamp(cx + rr*Math.cos(a) + sTan*rnorm(rng), 0,1),
                 y: clamp(cy + rr*Math.sin(a) + sTan*rnorm(rng), 0,1) });
    }
    for (let i=0; i<n2; i++){
      const a  = rng()*2*Math.PI;
      const rr = r2 + sRad*rnorm(rng);
      pts.push({ x: clamp(cx + rr*Math.cos(a) + sTan*rnorm(rng), 0,1),
                 y: clamp(cy + rr*Math.sin(a) + sTan*rnorm(rng), 0,1) });
    }
    return pts;
  }
  function addNoise(points, rng, ratio){
    const k = Math.round(points.length*ratio);
    for(let i=0;i<k;i++) points.push({x:rng(), y:rng(), noise:true});
    return points;
  }

  // ====== DBSCAN ======
  function dbscan(points, eps, minPts){
    const n = points.length, eps2 = eps*eps;
    const visited = new Array(n).fill(false);
    const assigned= new Array(n).fill(false);
    const isCore  = new Array(n).fill(false);
    const neighbors = new Array(n);

    for(let i=0;i<n;i++){
      const neigh = [];
      for(let j=0;j<n;j++){
        if(i===j) continue;
        if(dist2(points[i], points[j]) <= eps2) neigh.push(j);
      }
      neighbors[i] = neigh;
      if(neigh.length+1 >= minPts) isCore[i] = true;
    }

    let clusterId = 0;
    const labels = new Array(n).fill(-1);

    for(let i=0;i<n;i++){
      if(visited[i]) continue;
      visited[i]=true;
      if(!isCore[i]) continue;

      labels[i] = clusterId;
      assigned[i]=true;

      const queue=[...neighbors[i]];
      while(queue.length){
        const q = queue.pop();
        if(!visited[q]){
          visited[q]=true;
          if(isCore[q]) queue.push(...neighbors[q]);
        }
        if(!assigned[q]){
          labels[q]=clusterId;
          assigned[q]=true;
        }
      }
      clusterId++;
    }

    for(let i=0;i<n;i++){
      if(assigned[i]) continue;
      let cid = -1;
      for(const j of neighbors[i]){
        if(isCore[j] && labels[j]!==-1){ cid = labels[j]; break; }
      }
      labels[i] = cid;
    }

    return points.map((p, idx) => ({
      ...p,
      cid: labels[idx],
      core: isCore[idx],
      noise: labels[idx]===-1
    }));
  }

  // ====== K-distance helper ======
  function kDistance(points, k){
    const arr = [];
    for(let i=0;i<points.length;i++){
      const dists = [];
      for(let j=0;j<points.length;j++){
        if(i===j) continue;
        dists.push(dist(points[i], points[j]));
      }
      dists.sort((a,b)=>a-b);
      const kth = dists[Math.max(0, Math.min(k-1, dists.length-1))];
      arr.push(kth);
    }
    arr.sort((a,b)=> b-a);
    return arr.map((v,i)=> ({i, v}));
  }

  // ====== K-means (k-means++ init) ======
  function kmeansPPInit(points, k, rng){
    const n = points.length;
    const centers = [];
    centers.push(points[(rng()*n)|0]);
    const d2 = new Array(n).fill(0);
    while(centers.length < k){
      for(let i=0;i<n;i++){
        let best = Infinity;
        for(const c of centers){
          const vv = dist2(points[i], c);
          if(vv<best) best = vv;
        }
        d2[i] = best;
      }
      const sum = d2.reduce((s,x)=>s+x,0) || 1e-12;
      let r = rng()*sum;
      let pick = 0;
      for(let i=0;i<n;i++){ r -= d2[i]; if(r<=0){ pick=i; break; } }
      centers.push({x: points[pick].x, y: points[pick].y});
    }
    return centers;
  }
  function inertia(points, labels, centers){
    let tot=0;
    for(let i=0;i<points.length;i++){
      const c = centers[labels[i]];
      tot += dist2(points[i], c);
    }
    return tot;
  }
  function kmeans(points, k, maxIters, rng){
    const n = points.length;
    k = Math.max(1, Math.min(k, n));
    let centers = kmeansPPInit(points, k, rng).map(c => ({x:c.x, y:c.y}));
    let labels  = new Array(n).fill(0);

    for(let iter=0; iter<maxIters; iter++){
      let changed = false;
      for(let i=0;i<n;i++){
        let best=-1, bestd=Infinity;
        for(let c=0;c<k;c++){
          const d = dist2(points[i], centers[c]);
          if(d < bestd){ bestd=d; best=c; }
        }
        if(labels[i] !== best){ labels[i]=best; changed = true; }
      }
      const sum = Array.from({length:k}, _ => ({x:0,y:0,c:0}));
      for(let i=0;i<n;i++){ const c=labels[i]; sum[c].x += points[i].x; sum[c].y += points[i].y; sum[c].c++; }
      for(let c=0;c<k;c++){
        if(sum[c].c>0){
          centers[c].x = sum[c].x / sum[c].c;
          centers[c].y = sum[c].y / sum[c].c;
        }
      }
      if(!changed) break;
    }
    const labeled = points.map((p,i)=> ({...p, cid: labels[i], core:false, noise:false}));
    const I = inertia(points, labels, centers);
    return {labeled, centers, inertia: I};
  }

  // ====== Hierarchical core (agglomerative) ======
  function agglomerative(points, linkage="single"){
    const n = points.length;
    const size = [], alive = [], centroid = [];
    for(let i=0;i<n;i++){ size[i]=1; alive[i]=true; centroid[i]={x:points[i].x, y:points[i].y}; }

    const N = 2*n-1;
    const distMat = Array.from({length:N}, _ => new Map());
    function setD(i,j,val){ if(i>j){const t=i;i=j;j=t;} distMat[i].set(j,val); }
    function getD(i,j){ if(i===j) return 0; if(i>j){const t=i;i=j;j=t;} return distMat[i].get(j); }

    const useSq = (linkage==="ward");
    for(let i=0;i<n;i++){
      for(let j=i+1;j<n;j++){
        const d = useSq ? dist2(points[i], points[j]) : dist(points[i], points[j]);
        setD(i,j,d);
      }
    }

    const merges = [];
    let nextId = n;

    function pickMin(){
      let bi=-1, bj=-1, bd=Infinity;
      for(let i=0;i<nextId;i++){
        if(!alive[i]) continue;
        const row = distMat[i];
        for(const [j,d] of row){
          if(j>=nextId || !alive[j]) continue;
          if(d < bd){ bd=d; bi=i; bj=j; }
        }
      }
      return [bi,bj,bd];
    }

    while(true){
      let aliveCnt=0;
      for(let i=0;i<nextId;i++) if(alive[i]) aliveCnt++;
      if(aliveCnt<=1) break;

      const [i,j,d] = pickMin();
      if(i===-1) break;

      const m = nextId++;
      alive[i]=false; alive[j]=false; alive[m]=true;
      const si=size[i], sj=size[j];
      size[m]=si+sj;
      centroid[m] = { x:(centroid[i].x*si + centroid[j].x*sj)/(si+sj),
                      y:(centroid[i].y*si + centroid[j].y*sj)/(si+sj) };
      const height = (linkage==="ward") ? Math.sqrt(d) : d;
      merges.push({left:i, right:j, height, newId:m, size:size[m]});

      for(let k=0;k<nextId;k++){
        if(!alive[k] || k===m) continue;
        let dik = getD(i,k), djk = getD(j,k);
        if(dik===undefined) dik = (linkage==="ward") ? dist2(centroid[i], centroid[k]) : dist(centroid[i], centroid[k]);
        if(djk===undefined) djk = (linkage==="ward") ? dist2(centroid[j], centroid[k]) : dist(centroid[j], centroid[k]);

        let dm;
        if(linkage==="single"){
          dm = Math.min(dik, djk);
        } else if(linkage==="complete"){
          dm = Math.max(dik, djk);
        } else if(linkage==="average"){
          dm = (si/(si+sj))*dik + (sj/(si+sj))*djk;
        } else { // ward
          const sk = size[k];
          dm = ((si+sk)/(si+sj+sk))*dik + ((sj+sk)/(si+sj+sk))*djk - (sk/(si+sj+sk))*getD(i,j);
        }
        setD(m,k, dm);
      }
    }
    return {merges, nLeaves:n};
  }

  // ====== Label helpers ======
  function relabelConsecutive(points){
    const map = new Map(); let next=0;
    return points.map(p => {
      if(!map.has(p.cid)) map.set(p.cid, next++);
      return {...p, cid: map.get(p.cid)};
    });
  }
  function centroidsFromLabels(points, K){
    const cents = Array.from({length:K}, _=>({x:0,y:0,c:0}));
    for(const p of points){ const k=p.cid; if(k>=0 && k<K){ cents[k].x+=p.x; cents[k].y+=p.y; cents[k].c++; } }
    for(const c of cents){ if(c.c>0){ c.x/=c.c; c.y/=c.c; } else { c.x=NaN; c.y=NaN; } }
    return cents;
  }
  function centroidOfCluster(points, cid){
    let sx=0, sy=0, c=0;
    for(const p of points) if(p.cid===cid){ sx+=p.x; sy+=p.y; c++; }
    return c>0 ? {x:sx/c,y:sy/c,c} : {x:NaN,y:NaN,c:0};
  }

  // ====== Force exactly K clusters for Hierarchical ======
  function enforceExactK(labeled, K){
    labeled = relabelConsecutive(labeled);
    let m = new Set(labeled.map(p=>p.cid)).size;

    const counts = () => {
      const mapC = new Map();
      for (const p of labeled) mapC.set(p.cid, (mapC.get(p.cid)||0)+1);
      return mapC;
    };

    while (m < K){
      const cnt = counts();
      let big=-1, bs=-1;
      for(const [cid, c] of cnt){ if(c>bs){ bs=c; big=cid; } }
      if (big===-1) break;
      const cent = centroidOfCluster(labeled, big);
      let farIdx=-1, farD=-1;
      for(let i=0;i<labeled.length;i++){
        if(labeled[i].cid!==big) continue;
        const d = dist(labeled[i], cent);
        if(d>farD){ farD=d; farIdx=i; }
      }
      const newId = Math.max(...labeled.map(p=>p.cid))+1;
      if (farIdx>=0) labeled[farIdx] = {...labeled[farIdx], cid:newId};
      labeled = relabelConsecutive(labeled);
      m = new Set(labeled.map(p=>p.cid)).size;
    }

    while (m > K){
      const curIds = Array.from(new Set(labeled.map(p=>p.cid))).sort((a,b)=>a-b);
      const cents = curIds.map(cid => ({cid, ...centroidOfCluster(labeled, cid)}));
      let pa=-1, pb=-1, best=Infinity;
      for(let i=0;i<cents.length;i++){
        for(let j=i+1;j<cents.length;j++){
          const d = dist(cents[i], cents[j]);
          if(d<best){ best=d; pa=cents[i].cid; pb=cents[j].cid; }
        }
      }
      if (pa===-1 || pb===-1) break;
      labeled = labeled.map(p => p.cid===pb ? ({...p, cid: pa}) : p);
      labeled = relabelConsecutive(labeled);
      m = new Set(labeled.map(p=>p.cid)).size;
    }
    labeled = relabelConsecutive(labeled);
    return labeled;
  }

  // ====== Helper charts ======
  function renderKDistance(points, k){
    const arr = kDistance(points, k);
    return Plot.plot({
      width: 520, height: 220, marginLeft: 50, marginBottom: 40,
      x: {label: "points sorted (desc)"},
      y: {label: k + "-NN distance"},
      marks: [ Plot.line(arr, {x:"i", y:"v"}), Plot.dot(arr, {x:"i", y:"v", r:1.5}) ]
    });
  }

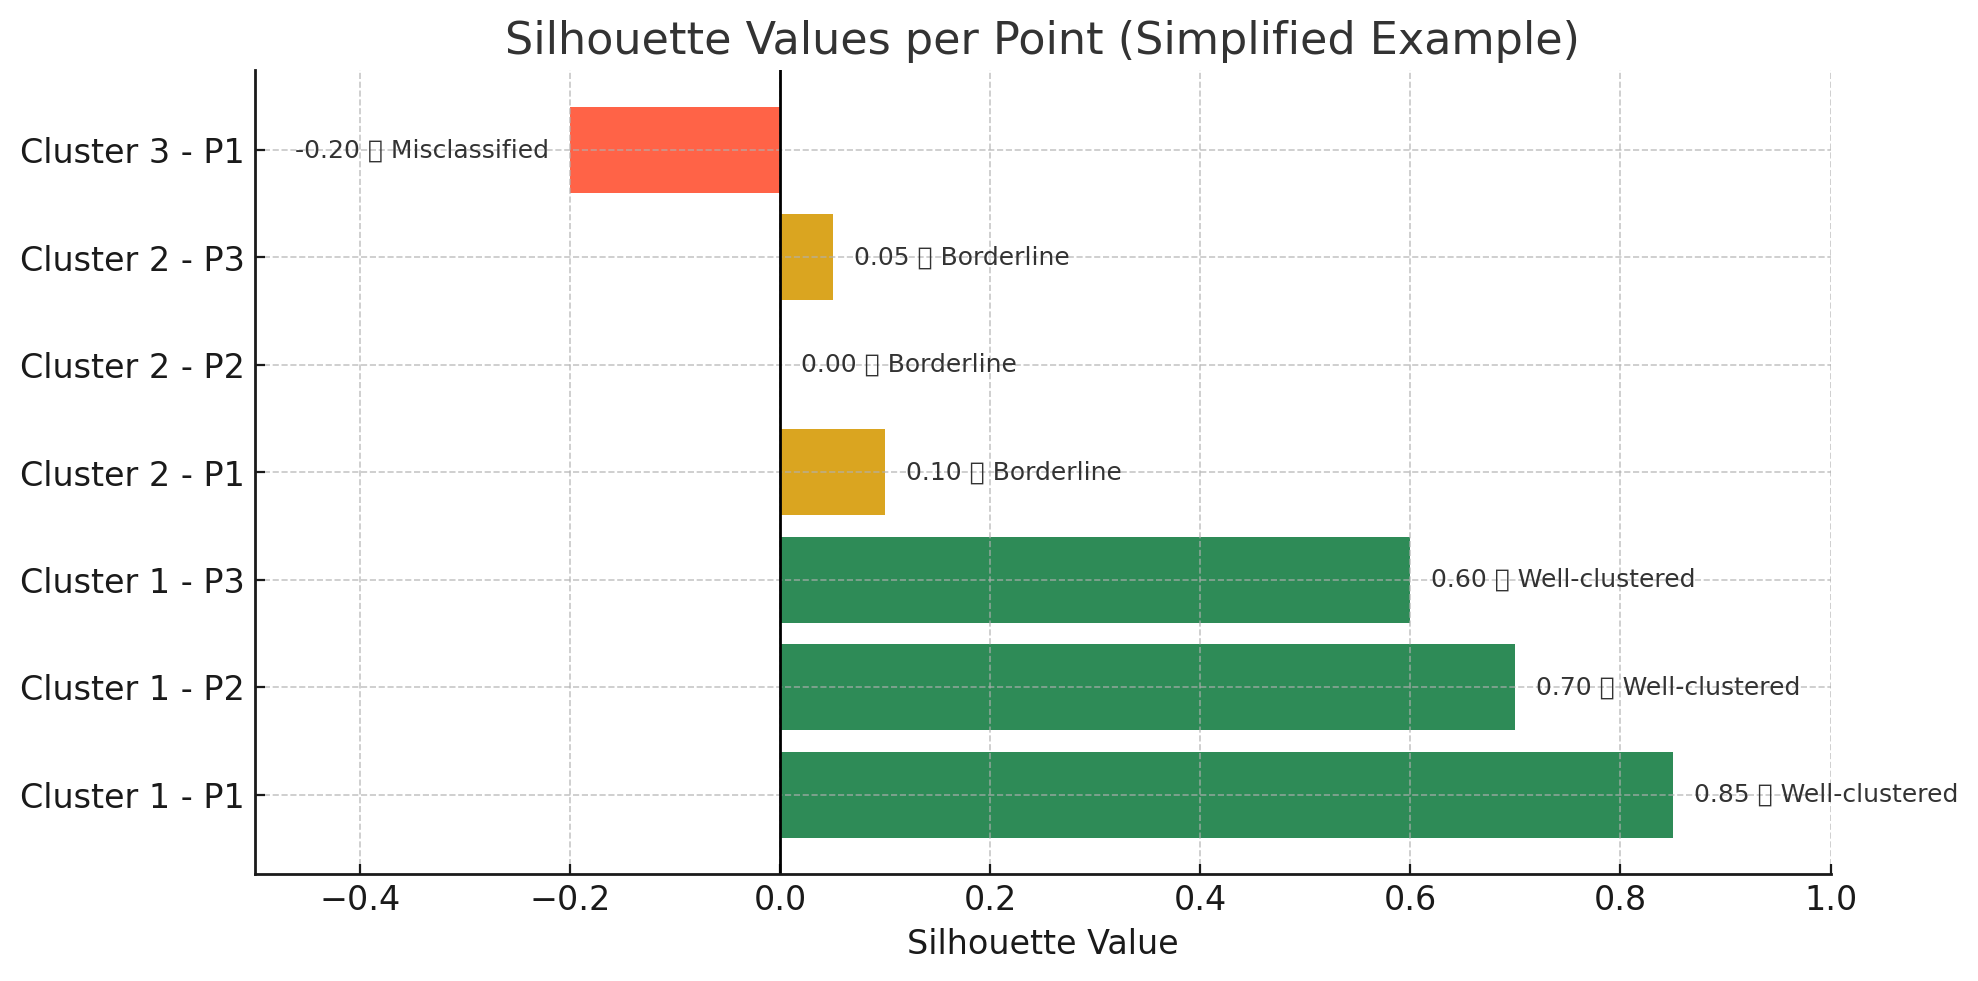
  function computeElbowAndSil(points, rng, maxIter=50){
    const ks = Array.from({length: 11}, (_,i)=> i+2); // 2..12
    const elbow = [];
    const sil   = [];
    for(const kk of ks){
      const {labeled, centers, inertia: I} = kmeans(points, kk, maxIter, rng);
      elbow.push({k: kk, inertia: I});
      const SAMP = Math.min(400, labeled.length);
      let step = Math.max(1, Math.floor(labeled.length / SAMP));
      let sumS = 0, cnt=0;
      for(let i=0;i<labeled.length; i+=step){
        const p = labeled[i], ci = p.cid;
        let a=0, aN=0, b=Infinity;
        for(let j=0;j<labeled.length;j++){
          if(i===j) continue;
          const d = dist(p, labeled[j]);
          if(labeled[j].cid === ci){ a += d; aN++; }
        }
        if(aN>0) a /= aN; else a = 0;
        const kmax = Math.max(...labeled.map(d=>d.cid));
        for(let cj=0; cj<=kmax; cj++){
          if(cj===ci) continue;
          let sum=0, n=0;
          for(let j=0;j<labeled.length;j++){
            if(labeled[j].cid===cj){ sum += dist(p, labeled[j]); n++; }
          }
          if(n>0){ const avg=sum/n; if(avg < b) b=avg; }
        }
        if(!isFinite(b)) b = a;
        const s = (b - a) / Math.max(a, b, 1e-12);
        sumS += s; cnt++;
      }
      sil.push({k: kk, s: (cnt ? sumS/cnt : 0)});
    }
    return {elbow, sil};
  }

  // ✅ These were missing:
  function renderElbow(elbow){
    return Plot.plot({
      width: 520, height: 220, marginLeft: 56, marginBottom: 40,
      x: {label: "k"}, y: {label: "inertia (lower is better)"},
      marks: [ Plot.line(elbow, {x:"k", y:"inertia"}), Plot.dot(elbow, {x:"k", y:"inertia"}) ]
    });
  }
  function renderSil(sil){
    return Plot.plot({
      width: 520, height: 220, marginLeft: 56, marginBottom: 40,
      x: {label: "k"}, y: {label: "silhouette (−1..1; higher is better)"},
      marks: [ Plot.line(sil, {x:"k", y:"s"}), Plot.dot(sil, {x:"k", y:"s"}) ]
    });
  }

  // ====== DRAW ======
  let resampleNonce = 0; // ensures Resample always changes data even with same Seed

  function draw(){
    const rng = mulberry32((seedS.value|0) ^ (resampleNonce*0x9e3779b9));
    const n   = nS.value|0;
    const shape = shapeS.value;
    const noiseRatio = noiseS.value;

    // data
    let pts;
    if (shape === "blobs")      pts = genBlobs(n, rng);
    else if (shape === "moons") pts = genMoons(n, rng);
    else                        pts = genCircles(n, rng);
    addNoise(pts, rng, noiseRatio);

    const algo = algoS.value;
    let labeled;
    let info = "";
    let kmeansCenters = null;

    if (algo === "DBSCAN"){
      labeled = dbscan(pts, epsS.value, minPtsS.value);
      const kFound = Math.max(-1, ...labeled.map(d=>d.cid)) + 1;
      const coreCnt = labeled.filter(d=>d.core).length;
      const noiseCnt= labeled.filter(d=>d.cid===-1).length;
      info = `Clusters: <b>${kFound}</b> | Core: ${coreCnt} | Noise: ${noiseCnt}
              <span style="color:#666"> (ε=${epsS.value.toFixed(3)}, minPts=${minPtsS.value}, n=${labeled.length}, ${shape})</span>`;
    } else if (algo === "K-means"){
      const out = kmeans(pts, kS.value|0, 50, rng); // fixed 50 iterations
      labeled = out.labeled;
      kmeansCenters = out.centers;
      const kFound = Math.max(-1, ...labeled.map(d=>d.cid)) + 1;
      info = `Clusters (K-means++, 50 iters): <b>${kFound}</b> | Inertia: ${out.inertia.toFixed(2)}
              <span style="color:#666"> (k=${kS.value}, n=${labeled.length}, ${shape})</span>`;
    } else {
      const linkage = linkageS.value;
      const K = hkS.value|0;

      const ptsCopy = pts; // use full set or subset inside agglomerative section
      const maxHC = 600;
      if (ptsCopy.length <= maxHC) {
        const {merges, nLeaves} = agglomerative(ptsCopy, linkage);
        const edges = merges.map(m => ({u:m.left, v:m.right, h:m.height})).sort((a,b)=> b.h - a.h);
        const cuts = new Set(); for(let i=0;i<Math.min(K-1, edges.length); i++) cuts.add(i);

        const parentUF = Array.from({length:2*nLeaves},(_,i)=> i);
        function find(x){ while(parentUF[x]!==x){ parentUF[x]=parentUF[parentUF[x]]; x=parentUF[x]; } return x; }
        function unite(a,b){ a=find(a); b=find(b); if(a!==b) parentUF[b]=a; }
        for(let idx=edges.length-1; idx>=0; idx--){ if(cuts.has(idx)) continue; const e = edges[idx]; unite(e.u, e.v); }
        const root2id = new Map(); let next=0;
        const labels = new Array(nLeaves);
        for(let i=0;i<nLeaves;i++){ const r = find(i); if(!root2id.has(r)) root2id.set(r, next++); labels[i] = root2id.get(r); }
        labeled = ptsCopy.map((p,i)=> ({...p, cid: labels[i], core:false, noise:false}));
        labeled = enforceExactK(labeled, K);
      } else {
        const rngLoc = mulberry32(((seedS.value|0) ^ (resampleNonce*0x9e3779b9)) + 0xabc123);
        const idxs = Array.from({length:ptsCopy.length}, (_,i)=>i);
        for(let i=idxs.length-1;i>0;i--){ const j=(rngLoc()*(i+1))|0; [idxs[i],idxs[j]]=[idxs[j],idxs[i]]; }
        const take = idxs.slice(0, maxHC);
        const sub  = take.map(i => ptsCopy[i]);

        const {merges, nLeaves} = agglomerative(sub, linkage);
        const edges = merges.map(m => ({u:m.left, v:m.right, h:m.height})).sort((a,b)=> b.h - a.h);
        const cuts = new Set(); for(let i=0;i<Math.min(K-1, edges.length); i++) cuts.add(i);
        const parentUF = Array.from({length:2*nLeaves},(_,i)=> i);
        function find(x){ while(parentUF[x]!==x){ parentUF[x]=parentUF[parentUF[x]]; x=parentUF[x]; } return x; }
        function unite(a,b){ a=find(a); b=find(b); if(a!==b) parentUF[b]=a; }
        for(let idx=edges.length-1; idx>=0; idx--){ if(cuts.has(idx)) continue; const e = edges[idx]; unite(e.u, e.v); }
        const root2id = new Map(); let next=0;
        const labelsSub = new Array(nLeaves);
        for(let i=0;i<nLeaves;i++){ const r = find(i); if(!root2id.has(r)) root2id.set(r, next++); labelsSub[i] = root2id.get(r); }
        let labeledSub = sub.map((p,i)=> ({...p, cid: labelsSub[i], core:false, noise:false}));
        labeledSub = relabelConsecutive(labeledSub);

        let cents = centroidsFromLabels(labeledSub, K);
        for(let i=0;i<cents.length;i++){
          if(!isFinite(cents[i].x) || !isFinite(cents[i].y)){
            const r = (rngLoc()*sub.length)|0;
            cents[i] = {x: sub[r].x, y: sub[r].y, c:1};
          }
        }

        labeled = ptsCopy.map(p=>{
          let best=-1, bd=Infinity;
          for(let cId=0;cId<K;cId++){
            const c = cents[cId];
            const d = (p.x-c.x)*(p.x-c.x) + (p.y-c.y)*(p.y-c.y);
            if(d<bd){ bd=d; best=cId; }
          }
          return {...p, cid: best, core:false, noise:false};
        });

        labeled = enforceExactK(labeled, K);
      }

      const kFound = new Set(labeled.map(d=>d.cid)).size;
      info = `Clusters (Hierarchical, ${linkage}): <b>${kFound}</b>
              <span style="color:#666"> (k=${hkS.value}, n=${labeled.length}, ${shape})</span>`;
    }

    // ====== Render main scatter ======
    plotDiv.innerHTML = "";
    const marks = [];
    if (algo === "DBSCAN"){
      marks.push(Plot.dot(labeled.filter(d=>d.cid===-1), {x:"x", y:"y", r:2.8, fill:"#bbb", stroke:"white", title: d=> "noise"}));
      marks.push(Plot.dot(labeled.filter(d=>d.cid!==-1 && !d.core), {x:"x", y:"y", r:3.3, fill: d=> colorFor(d.cid), stroke:"white", title: d=>`cluster ${d.cid} (border)`}));
      marks.push(Plot.dot(labeled.filter(d=>d.core && d.cid!==-1), {x:"x", y:"y", r:4.8, fill: d=> colorFor(d.cid), stroke:"black", title: d=>`cluster ${d.cid} (core)`}));
      marks.push(Plot.text([{x:0.06,y:0.94,label:"● core, ● border, ○ noise"}], {x:"x",y:"y",text:"label",dy:-8,fill:"#444"}));
    } else {
      marks.push(Plot.dot(labeled, {x:"x", y:"y", r:3.6, fill: d=> colorFor(d.cid), stroke:"white", title: d=>`cluster ${d.cid}`}));
      if (algo === "K-means" && Array.isArray(kmeansCenters)){
        marks.push(Plot.dot(kmeansCenters, {x:"x", y:"y", r:7.5, fill:"white", stroke:"black", strokeWidth:2}));
        marks.push(Plot.text(kmeansCenters.map(c => ({x:c.x, y:c.y, label:"×"})), {x:"x", y:"y", text:"label", dy:3, fill:"black"}));
      }
    }
    plotDiv.append(Plot.plot({
      width: 1060, height: 560, marginLeft: 56, marginBottom: 44,
      x: {domain: [0,1], grid: true, label: "x₁"},
      y: {domain: [0,1], grid: true, label: "x₂"},
      marks
    }));

    // ====== Helper dashboard ======
    dash.innerHTML = "";
    if (algo === "DBSCAN" && showKDist.value){
      dash.append(renderKDistance(pts, minPtsS.value|0));
      dash.append(html`<div style="align-self:center;color:#666;">Tip: Set ε near the “elbow point” of the graph.</div>`);
    } else if (algo === "K-means" && showElbow.value){
      const {elbow, sil} = computeElbowAndSil(pts, mulberry32((seedS.value|0) ^ (resampleNonce*0x9e3779b9) ^ 0x517cc1), 50);
      dash.append(renderElbow(elbow));
      dash.append(renderSil(sil));
    }

    // ====== Note & soften irrelevant controls ======
    note.innerHTML = info + (resampleNonce>0 ? ` <span style="color:#0a7">• resampled×${resampleNonce}</span>` : "");

    const isDB = (algo==="DBSCAN"), isKM=(algo==="K-means"), isHC=(algo==="Hierarchical");
    epsS.style.opacity      = isDB ? 1 : 0.35;
    minPtsS.style.opacity   = isDB ? 1 : 0.35;
    showKDist.style.opacity = isDB ? 1 : 0.2;

    kS.style.opacity        = isKM ? 1 : 0.35;

    hkS.style.opacity       = isHC ? 1 : 0.35;
    linkageS.style.opacity  = isHC ? 1 : 0.35;
  }

  // events
  [algoS,seedS,nS,shapeS,noiseS,kS,epsS,minPtsS,showKDist,hkS,linkageS,showElbow]
    .forEach(el => el.addEventListener("input", draw));

  // Resample always changes RNG stream even if Seed unchanged
  btnRes.addEventListener("click", () => { resampleNonce++; draw(); });

  // initial
  draw();
  return box;
})()